
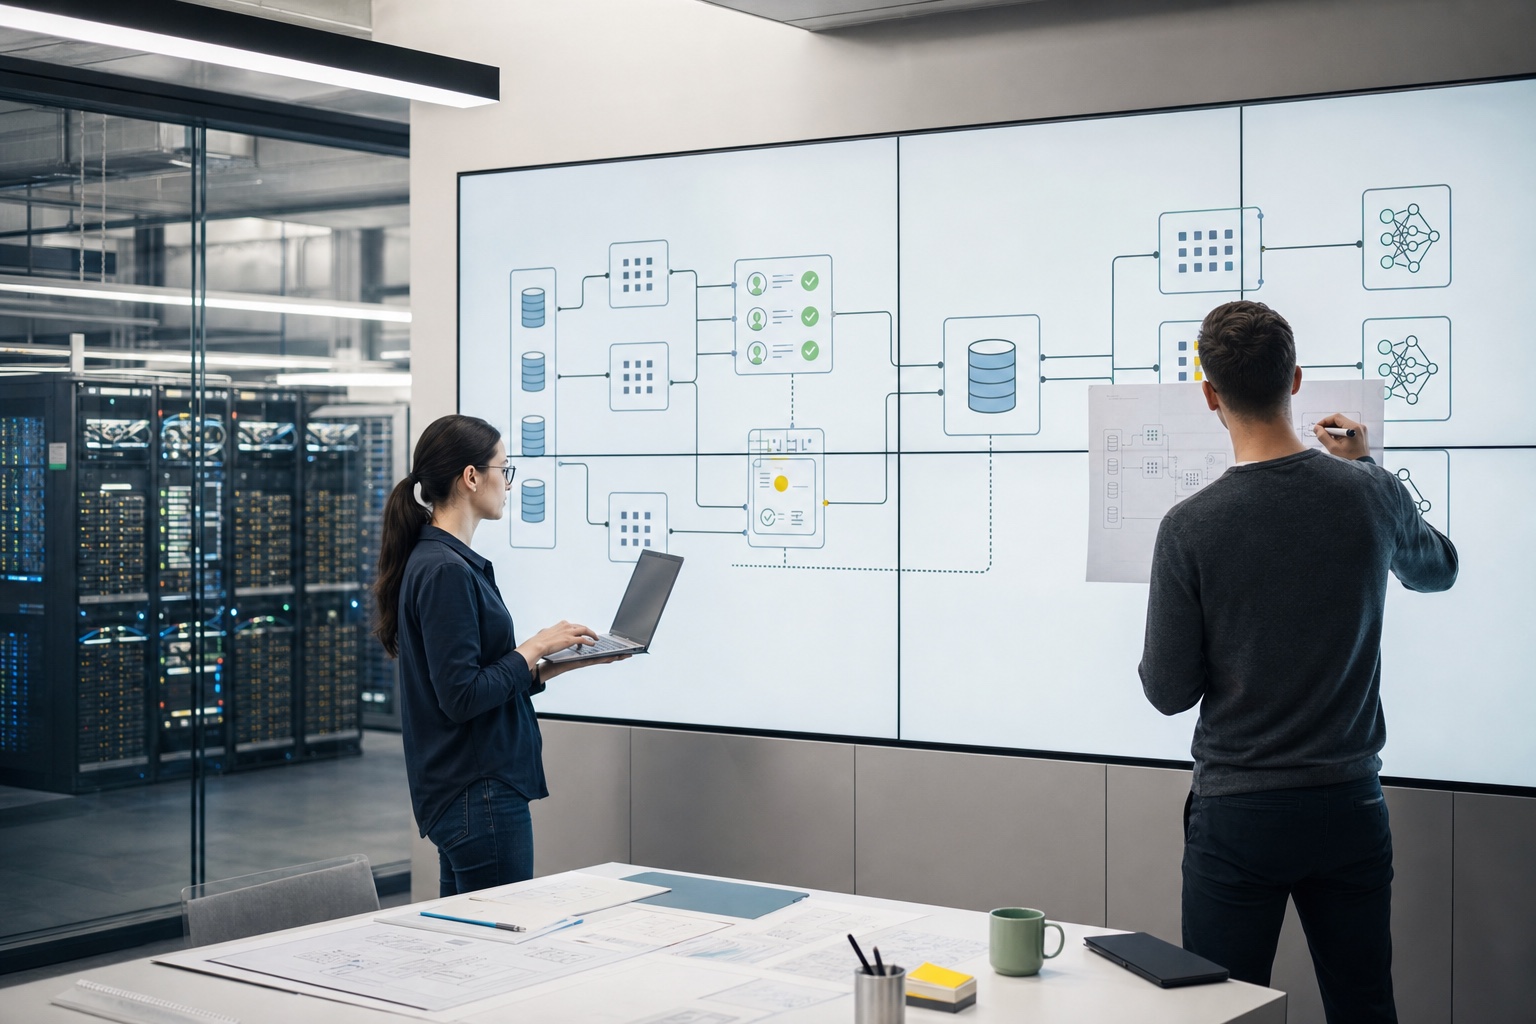
Data architecture for AI: quality, RAG, pipelines and operations
From source to evaluation, the components required to supply an AI application with reliable, observable and governed data.
dataarchitectureragqualitymlops
Category
Databases, pipelines, analytics, ML ops and data quality.
Databases, pipelines, analytics and MLOps are analysed as parts of one system. We cover reliability, governance and the quality required to support useful decisions.
Reference guide
From source to evaluation, the components required to supply an AI application with reliable, observable and governed data.
Five Rust optimizations cut the footprint of a DNS entry by 56% at Cloudflare. Here are the lessons for systems operating at extreme scale.
ClickHouse 26.7 exposes real query costs while optimizing Top-N aggregation and quantized vector search.
Cloudflare has opened the Radar Researcher beta, an assistant that queries network data in plain language and produces verifiable charts.
etcd 3.7 adds RangeStream and performance improvements while removing legacy components. A safe upgrade procedure for Kubernetes operators.
PostgreSQL 19 Beta 2 sharpens the changes expected this fall. Performance, observability and compatibility: a practical, low-risk test plan.
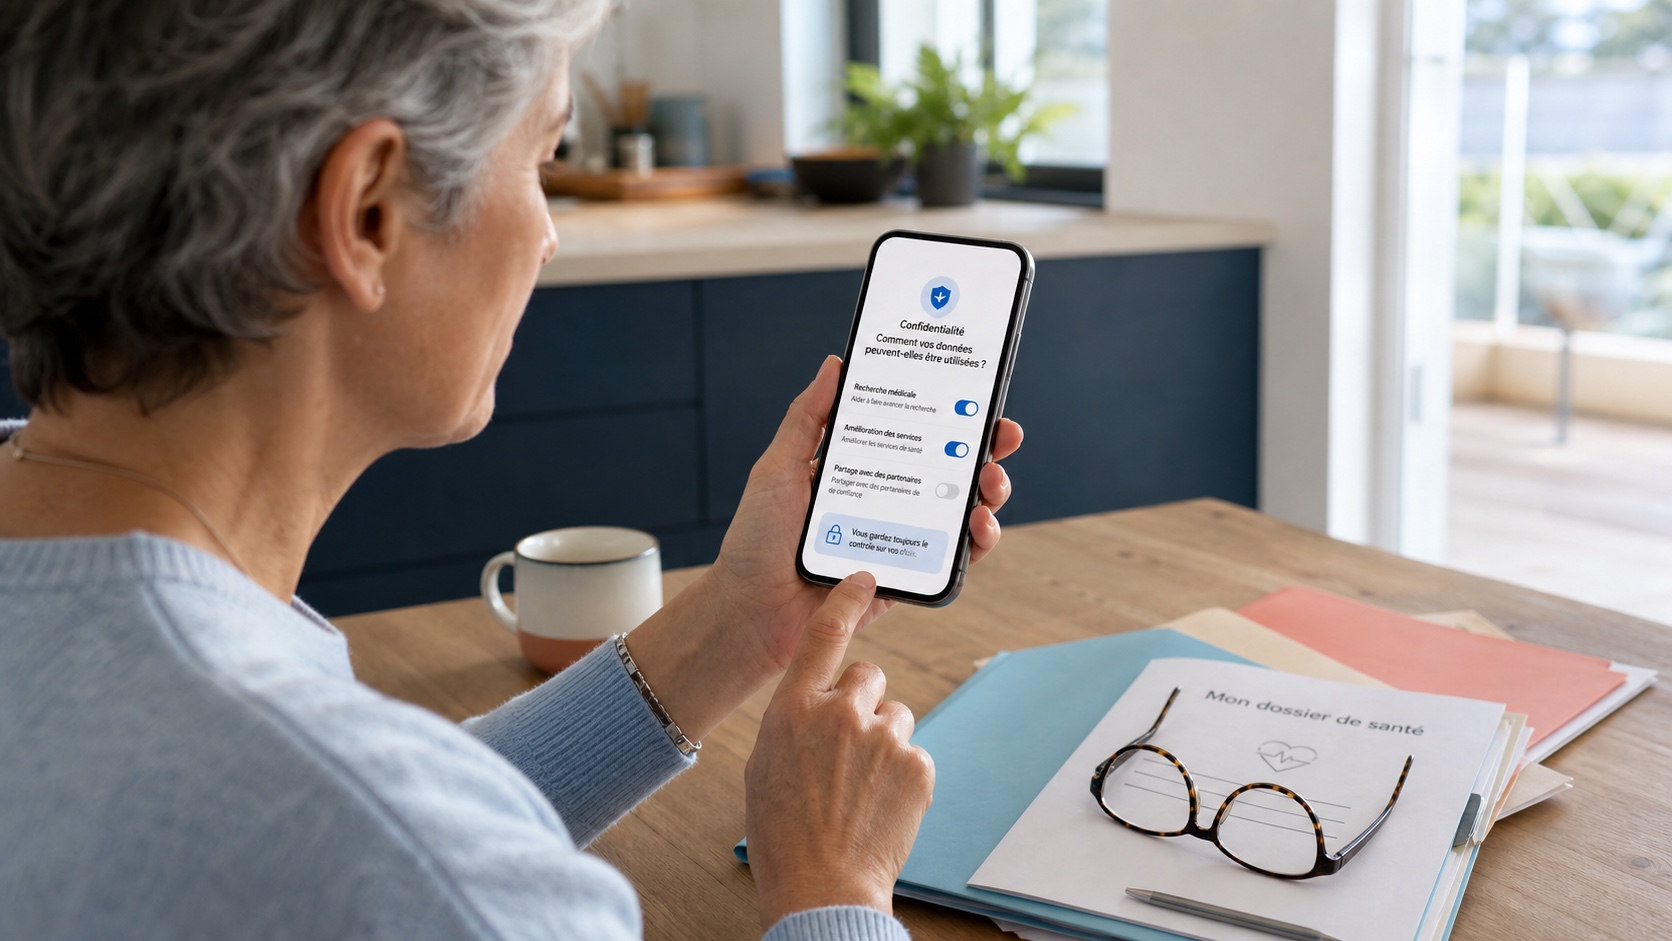
Doctolib's health-data research project starts in August. Data scope, pseudonymisation and the right to object: what patients should check.
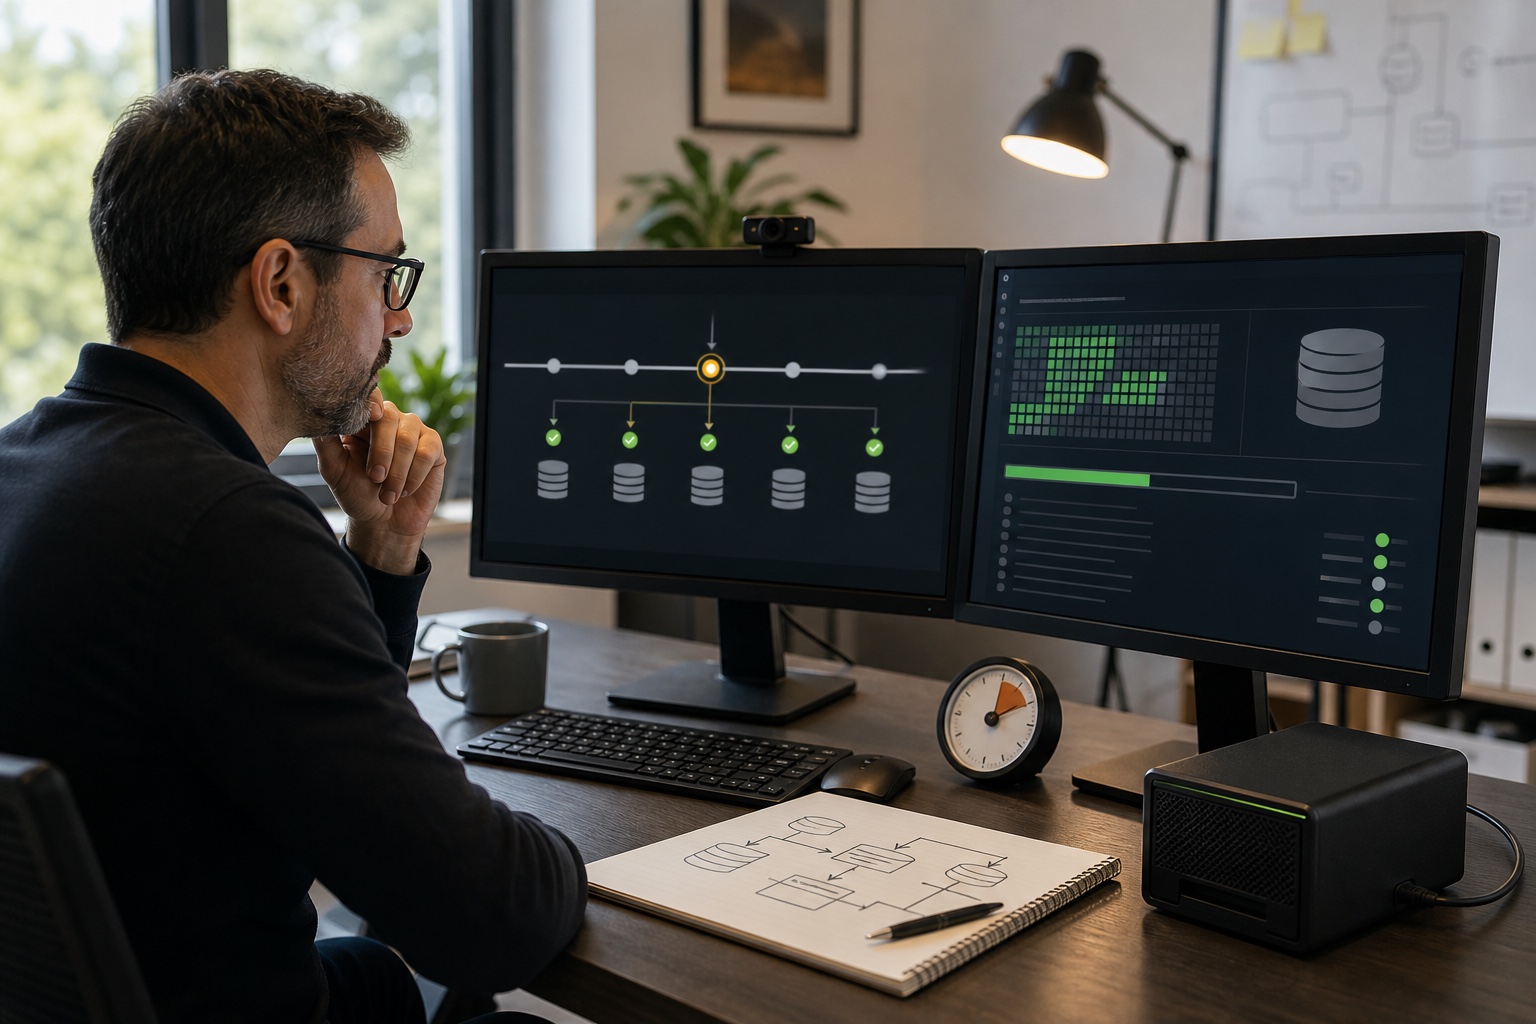
PostgreSQL, MySQL, Docker and PITR: an operational method for choosing backups, testing restoration and proving RPO/RTO targets.
Ingestion, hybrid search, reranking, citations and metrics: a complete method for building a reliable RAG system and deciding whether it is production-ready.
PostgreSQL 18 brings technical improvements that directly affect performance, migrations and data modeling.
Iceberg brings snapshots, schema evolution and hidden partitioning to large analytical datasets.
Adding a vector database does not make an assistant reliable. Documents, chunks and metadata often determine the result.
Duplicates, incomplete fields and contradictory definitions become more dangerous when a model reformulates them confidently.
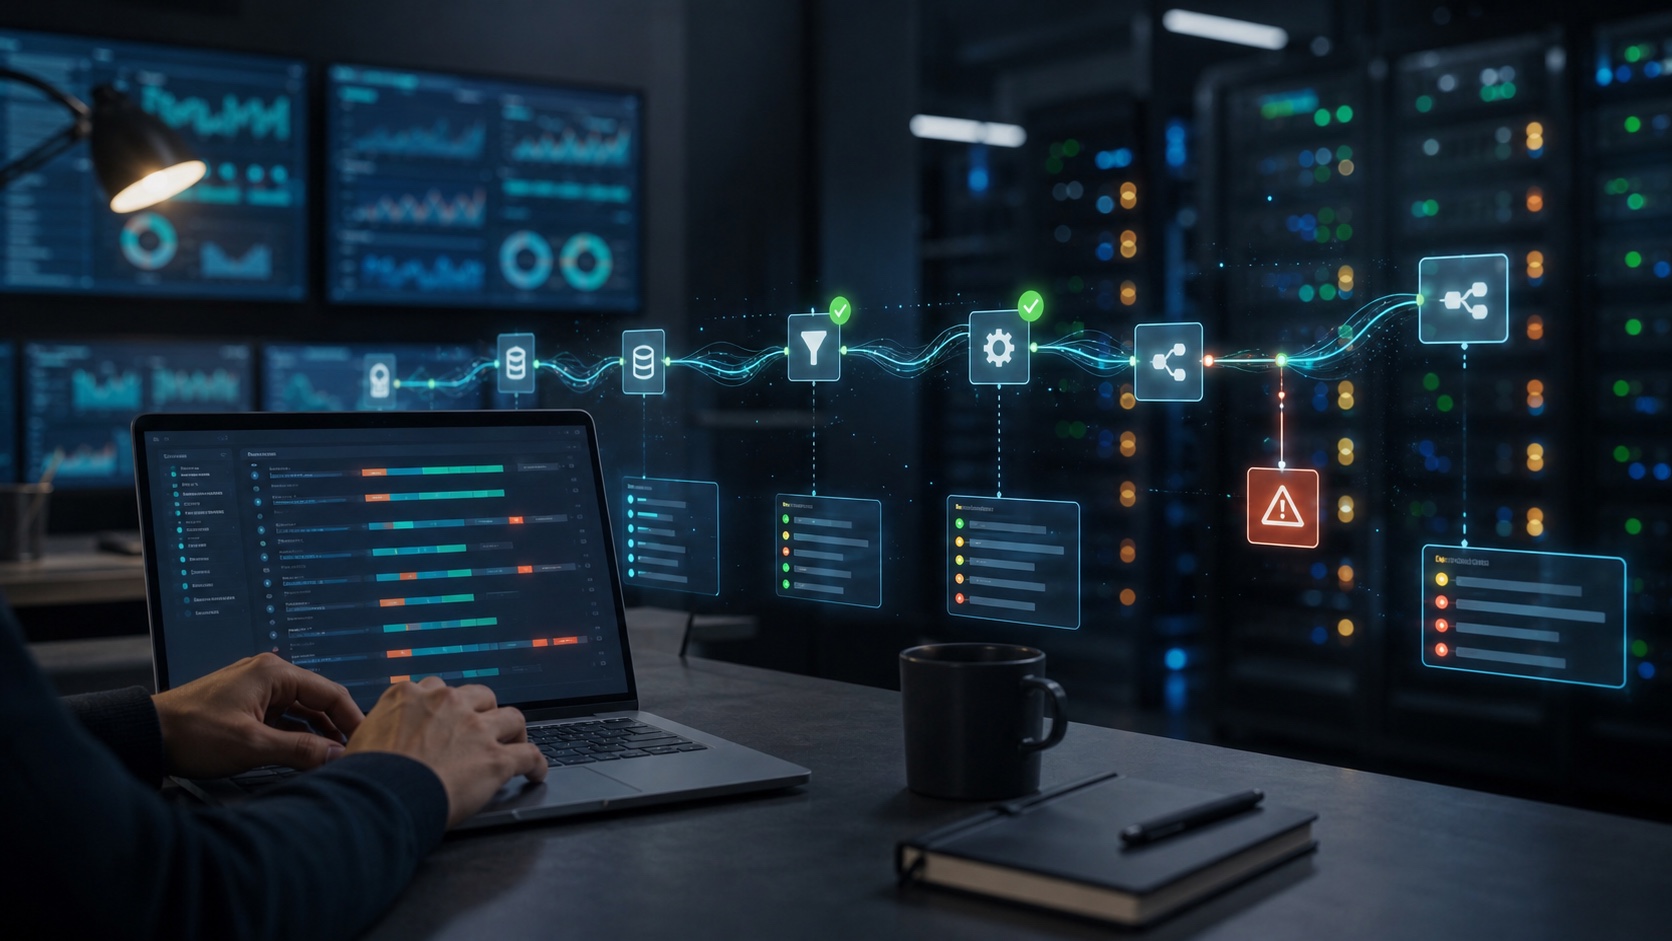
Teams monitor APIs with traces and metrics. Data pipelines deserve the same rigor to understand delays and errors.
The semantic layer promises shared metrics across BI, notebooks and AI. It mostly requires clear governance.
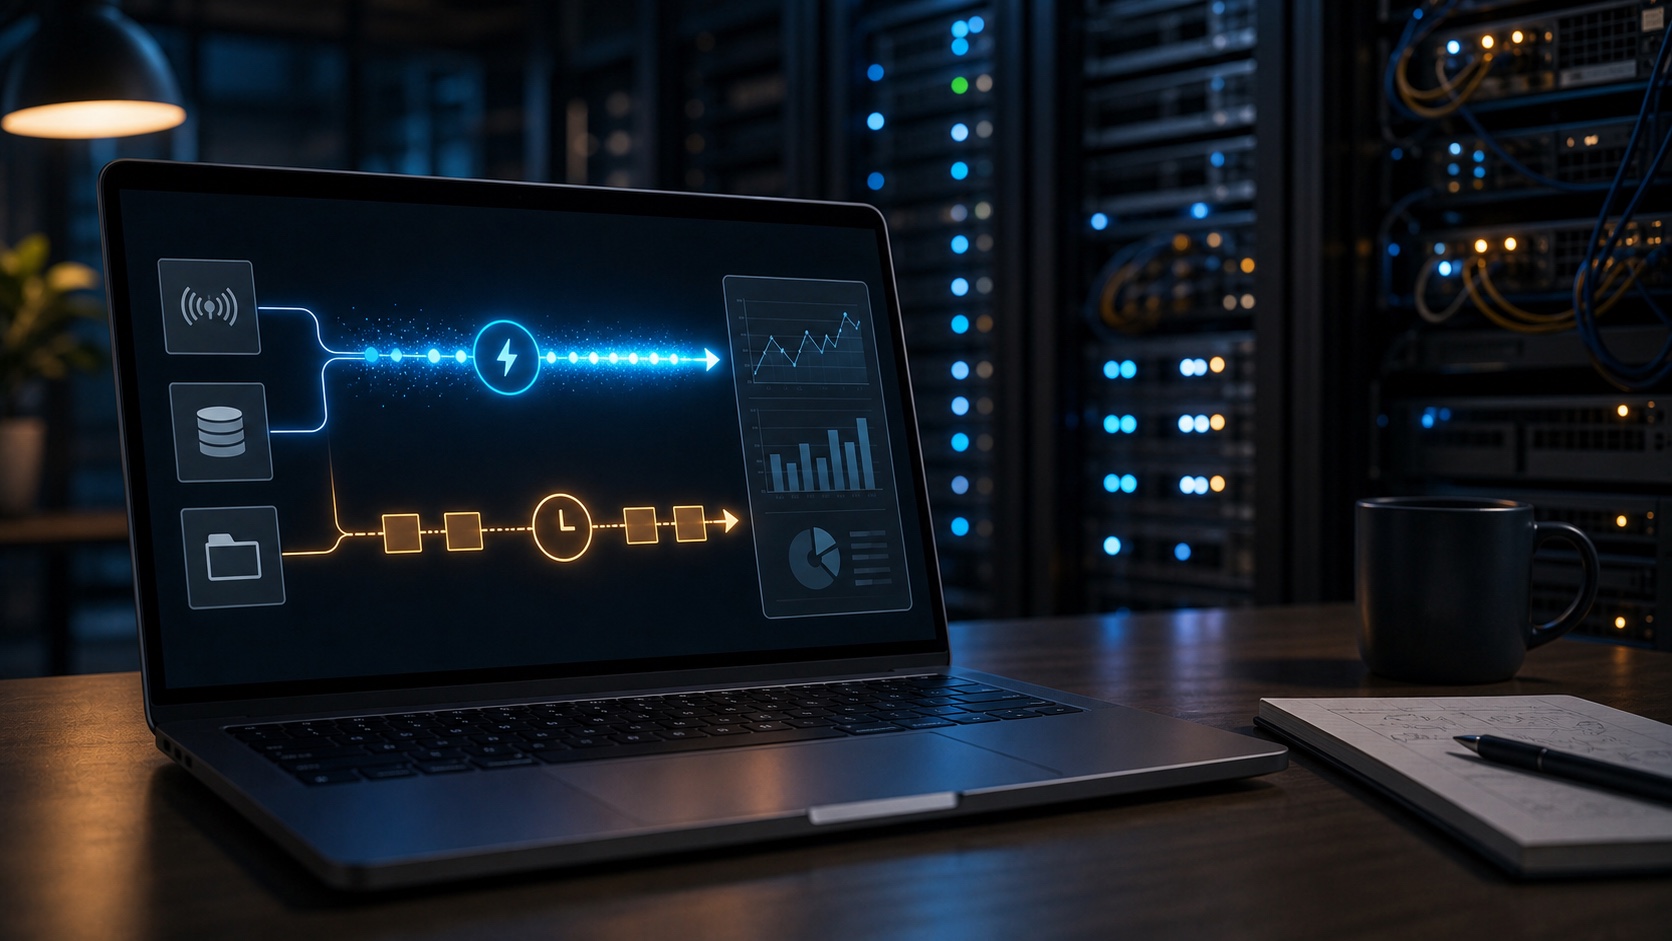
Streaming is powerful, but it adds cost and complexity. The right pace depends on the decision being made.
Teams want to give models more context. The best protection is sometimes not sending the data.
Synthetic data can protect privacy and speed up tests. It must still be compared with reality.
Latency and availability are not enough. In production, a model can stay online while getting worse.