
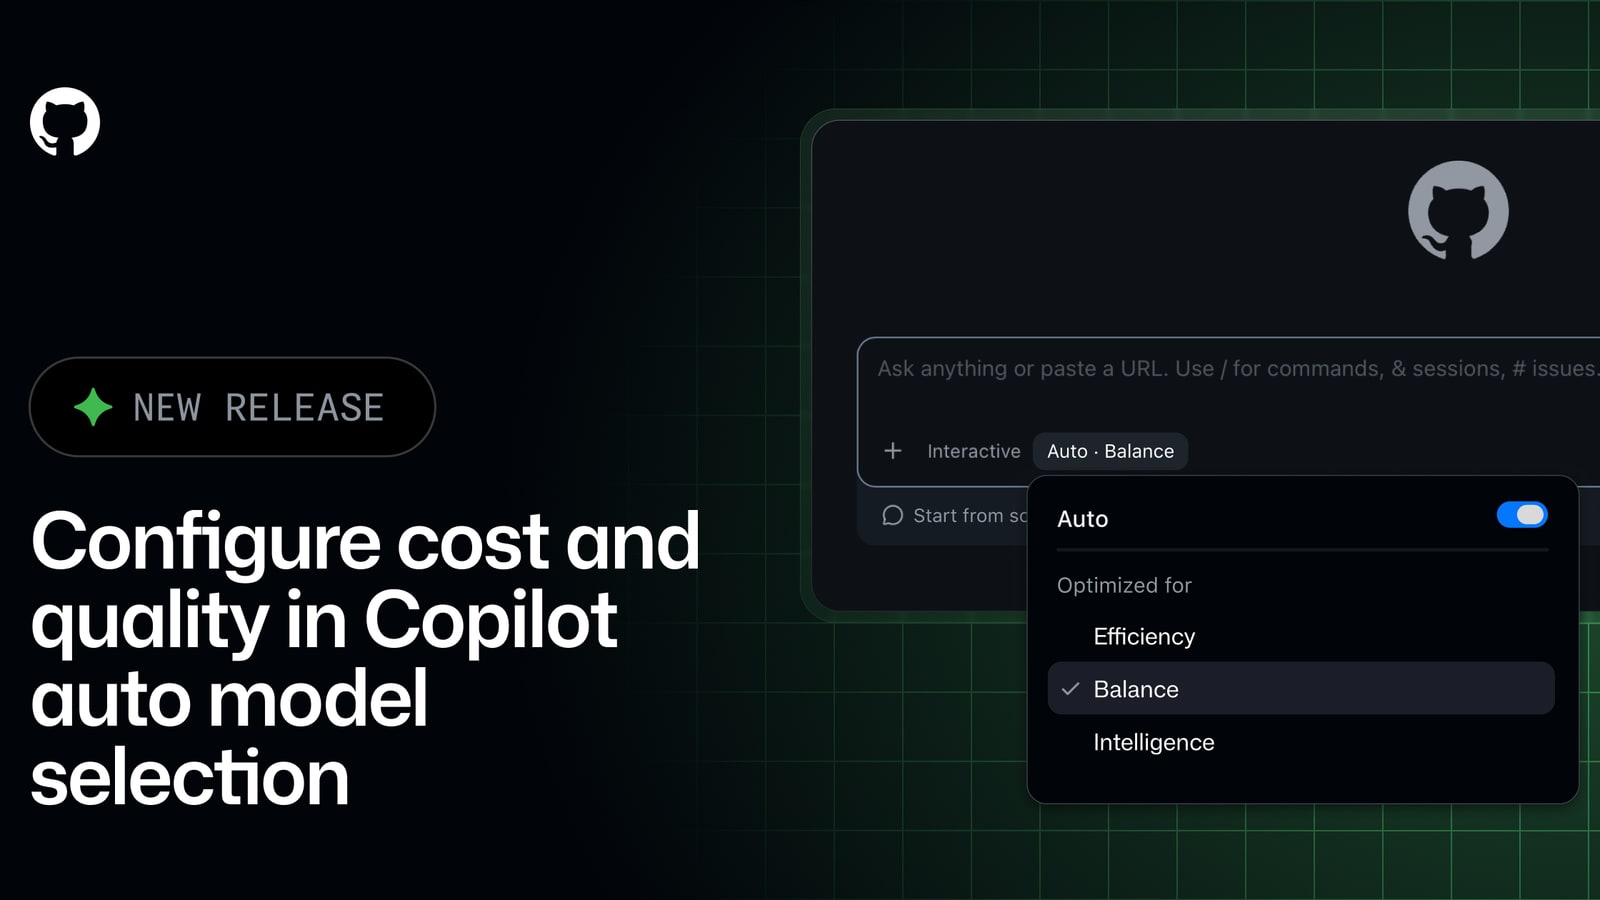
GitHub Copilot now displays token-spending indicators for each message and for the full session on the web. A new icon in the conversation exposes the consumed share of the quota without leaving the chat. GitHub has also made the window minimizable and recent conversations easier to resume.
This small interface change follows a much larger billing shift. Since June 1, 2026, standard Copilot billing has used AI credits calculated from the selected model and the number of tokens consumed. Per-message visibility finally helps users connect a specific request with its cost instead of discovering only an aggregate in billing settings.
The short answer
| Question | Answer |
|---|---|
| Where is spending visible? | In Copilot on GitHub.com, through an icon that breaks usage down by message and session. |
| Does every message cost the same? | No. The model, input size, output and tools involved all affect consumption. |
| Is the control available on every plan? | GitHub says the new conversation controls are generally available to all Copilot plans. |
| Does the counter replace account budgets? | No. It is a local signal; limits and budgets still live in billing or a compatible client. |
| Does a long conversation always cost more? | Often, because context can grow, but actual cost depends on what the model receives at each turn. |
| Should a session stop as soon as the counter rises? | Not automatically. Compare cost with useful work, and restart with clean context when history is no longer relevant. |
What the new indicator shows
In Copilot Chat on github.com, the spending icon opens a view of usage by message and by session. The first level helps identify a particularly heavy request. The second reveals accumulation across a conversation, making it more actionable than a monthly counter far removed from the prompt that generated the expense.
GitHub does not describe the changelog indicator as a final itemized invoice. It should be read as usage against the relevant Copilot quota and budget. Exact terms depend on the plan, billing account and policies configured by an organization.
The feature is announced for the web experience. Users should not assume that every IDE, the CLI and each integration expose the exact same view at the same time. Central billing settings remain the source of truth for aggregate usage.
Why context length matters
A model receives input tokens and generates output tokens. The input can contain more than the user's last sentence: previous messages, file excerpts, instructions, tool results and other context selected by Copilot may all be included. A conversation that drifts between topics can therefore keep carrying history that no longer helps.
Asking “fix this bug” without naming a file may trigger broad exploration. Providing the path, expected behavior, error and relevant tests gives the model a clearer target. A precise prompt is not necessarily shorter in characters, but it can prevent several rounds of searching and clarification.
Conversely, splitting one coherent task into dozens of tiny messages can cost more than a structured request. The useful target is not the shortest prompt. It is the least computation required to produce a verifiable result.
When to start a new conversation
A fresh session is useful when the objective changes, earlier decisions no longer apply or Copilot keeps reasoning from an abandoned assumption. It reduces historical context and makes the goal easier to understand. Constraints that remain valid must still be transferred, or the model will need to rediscover them.
Before closing a long session, summarize the useful state: changed files, decisions, outstanding tests and blockers. That summary can seed the next chat. Continuity then becomes deliberate instead of consisting of dozens of turns from which only a small fraction remains relevant.
The new minimize button does not reduce usage by itself. It lets users browse GitHub while a response is in progress and return to the conversation later. A minimized session is still the same session; it resets neither context nor its counter.
AI credits and legacy premium requests
GitHub's documentation now distinguishes standard usage-based billing from a legacy system retained for certain eligible annual Pro and Pro+ subscribers. Older pages describe premium requests and model multipliers. Since June 2026, the current system instead calculates credits from model choice and tokens.
The coexistence can confuse teams, especially when internal screenshots and procedures describe the old system. Before interpreting a number, check the account's plan and billing page. Two Copilot users can legitimately see different units.
Rate limits are a separate mechanism again. They protect capacity and distribute access, so they can temporarily interrupt intensive use even when budget remains. A limit message does not necessarily mean that every monthly credit has been consumed.
Setting a cap before an agentic task
For Copilot CLI, GitHub documents an AI credit limit per session. It caps what an interactive session can spend and decreases as messages are processed. This guardrail is particularly useful when an agent can inspect a repository, invoke tools and iterate for an extended period.
The cap should be high enough to complete the work and low enough to stop an unproductive loop. A localized bug fix does not need the same budget as a framework migration or a security review across repositories. Teams benefit from a few simple task profiles instead of one universal number.
A spending limit does not replace permissions. An agent with access to a sensitive secret or destructive command can cause harm within a small budget. Cost limits, sandboxing, human review and least-privilege access address different risks.
A practical method for reducing wasted usage
- define the expected result and success criteria before opening chat;
- provide only the files, errors and constraints that matter;
- ask for a short plan when a task crosses several modules;
- verify the first result before requesting another broad iteration;
- stop exploration that repeats the same findings;
- open a new session when the objective changes;
- use a more expensive model only when complexity warrants it;
- set a session cap for long-running or autonomous tasks;
- compare spending with development and review time actually saved;
- monitor team trends in billing, not only one isolated chat.
This method does not attempt to minimize every call. A more expensive answer can be worthwhile if it prevents a regression or hours of investigation. The indicator exists to make that trade-off visible.
What teams can finally measure
Per-message cost enables straightforward experiments. A team can compare two prompting approaches on similar work, measure the effect of narrower context or identify tasks that consume substantial credits without producing a merged change. Results need several observations because one exchange varies with the code and model.
The counter should not become a raw individual performance target. Pressuring developers to display the lowest number would encourage underspecified requests, hide difficult work and ignore quality. Useful metrics connect consumption to accepted outcomes, review time, defects and delivery speed.
The new indicator does not solve Copilot financial governance on its own. It does, however, move the signal closer to the action that generates cost. That is a necessary step toward using development agents with an intentional budget instead of discovering a limit after the work has happened.
Join the discussion
Comments
Loading comments…